Hexashield AI: AI Red Teaming Platform for LLMs, RAG and AI Agents
Discover, red team and protect every LLM, RAG system and AI agent continuously, at runtime.
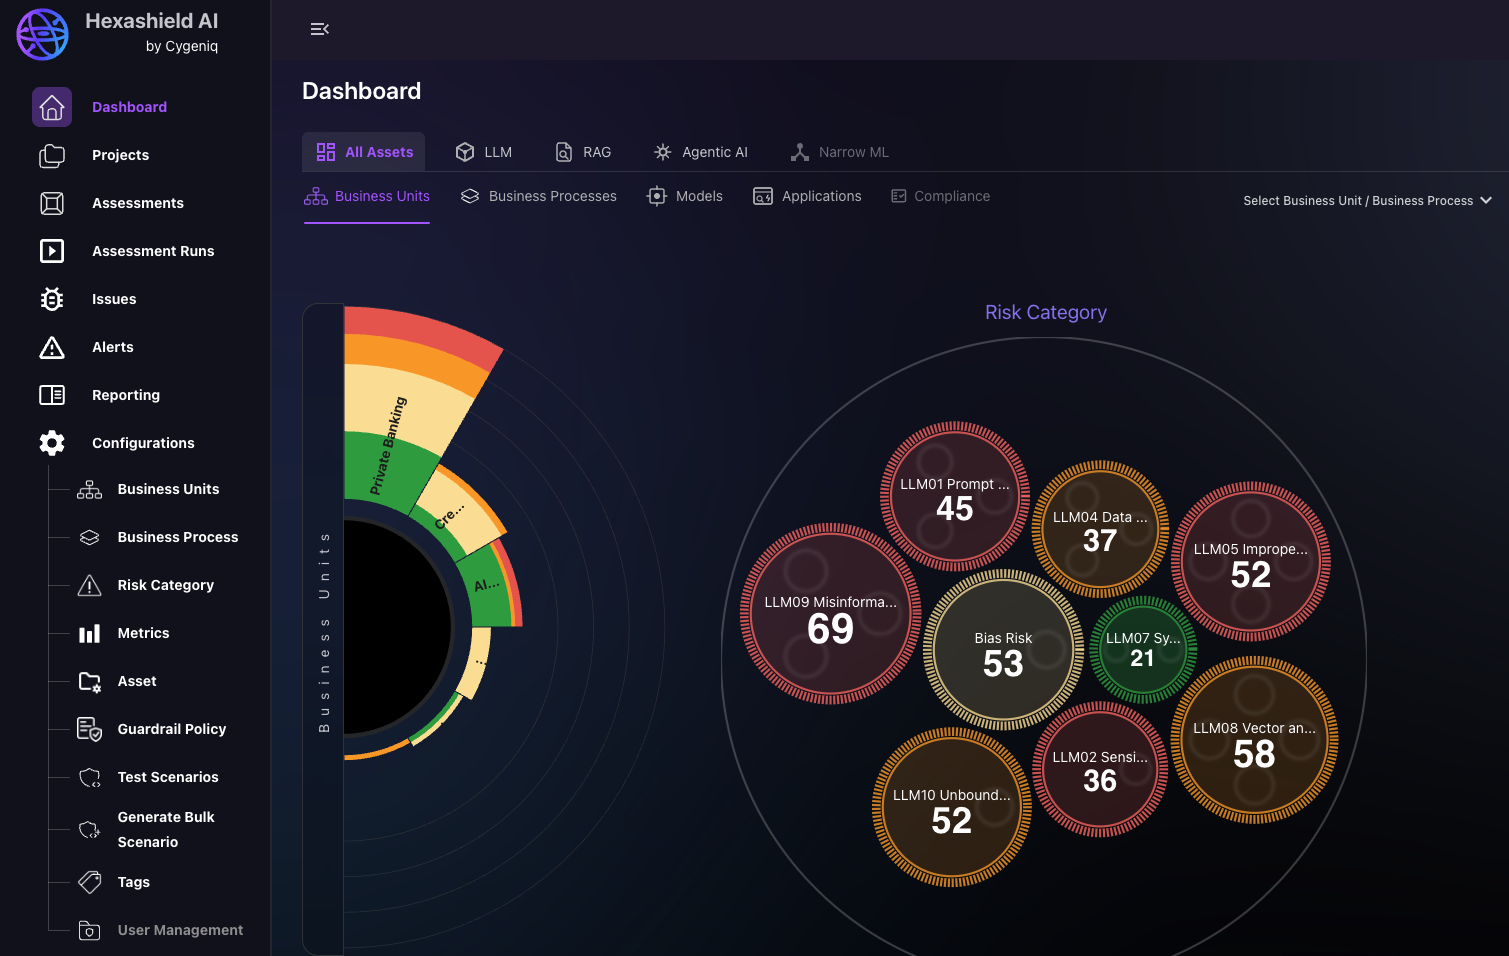
Cygeniq's AI red teaming platform for production AI systems, testing continuously at runtime
Hexashield AI combines LLM red teaming, GenAI red teaming, AI adversarial testing and AI runtime monitoring so security teams can continuously find unsafe behavior before an attacker does.
Hexashield AI connects to your AI Inventory and risk register, runs adversarial tests continuously against your LLMs, RAG pipelines and AI agents, then enforces runtime guardrails so prompt injection, jailbreaks and unsafe output get caught before they reach a user, not after. It also supports AI BOM creation, shadow AI detection and model drift monitoring across the AI estate.
Why Point-in-Time AI Red Teaming Leaves a Runtime Testing Gap
Point-in-time testing was not built for systems that change every day
A red team engagement once a quarter, or a manual review before launch, shows how a model behaved on the day it was tested. Prompt changes, model updates and new data sources can open a gap the next day. Hexashield AI treats AI red teaming as an ongoing process instead of a single event, so new exposure gets caught between assessments, not after an incident.
Static Test Libraries
A handful of manual prompts cannot cover how an LLM or agent might be pushed off course.
No Production Visibility
Most red teaming stops at a report. Nothing keeps watching the model once it ships.
No Audit Trail
When a regulator or a board asks for proof, screenshots and spreadsheets are not evidence.
AI Red Teaming, Runtime Monitoring and Guardrail Capabilities
Whether your team calls it LLM red teaming, GenAI red teaming or AI adversarial testing, the goal is the same: find unsafe behavior before an attacker does.
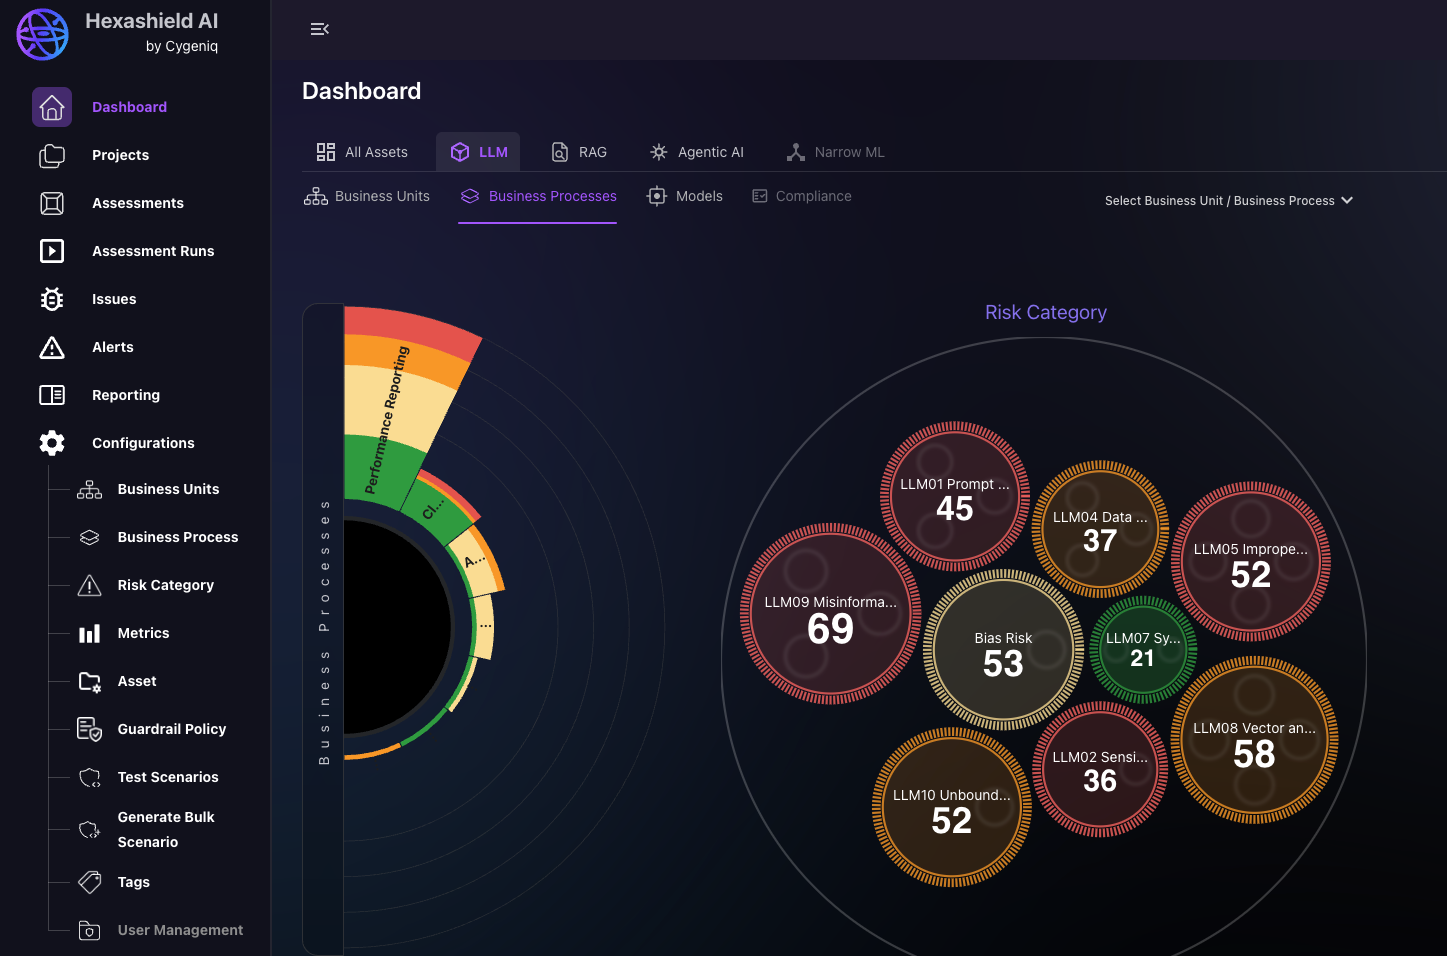
Adversarial and Autonomous Red Teaming
Continuous, agent-driven red teaming across copilots, RAG pipelines and autonomous AI agents, drawing on the GATSE™ library of 1M+ attack scenarios, not a single pre-launch pass.
Real-Time AI Risk Scoring
Every prompt, output and agent action is scored as it happens, so risk is a live number, not a quarterly estimate.
Runtime Guardrails and Policy
Inputs and outputs are checked for prompt injection, jailbreaks and unsafe content, with policy enforced inline for real-time prompt injection protection.
Runtime Risk and Vulnerability Monitoring
Models, RAG pipelines and agents are watched through continuous AI runtime monitoring, catching issues that only surface after deployment.
Risk Management and Simulation
Model abuse and attack paths are simulated across full AI workflows, not one prompt at a time.
Audit-Ready Risk Reporting
Evidence for risk, audit and regulatory teams is generated automatically and kept current.
AI Discovery, AI Inventory (BOM) and Shadow AI Detection
Every model, agent, copilot and RAG system is found and inventoried across IT and OT, including the ones nobody registered.
Model Validation and Drift Monitoring
Production models are checked against their validated behavior, so silent drift is caught before it reaches a decision.
See Hexashield AI Run Against Your Own AI Systems
Book a walkthrough of live risk scoring, adversarial testing and runtime guardrails, mapped to the systems you are already running.
How Hexashield AI Continuously Red Teams and Protects AI Systems
Onboard Your AI Systems
Connect LLMs, RAG pipelines and agents through API-based onboarding, and map each to the business unit it supports.
Run Adversarial Tests
Draw from the GATSE™ library of 1M+ attack scenarios covering prompt injection, jailbreaks, data exposure and model abuse, or add your own.
Enforce Guardrails at Runtime
Apply the same checks live at the input and output layer once a system is in production.
Score, Track and Report
Every run updates a risk score per model and business unit, and generates evidence a compliance or audit team can use directly.
Framework alignment: Testing scenarios are mapped to the OWASP Top 10 for LLM Applications, OWASP's agentic AI guidance and MITRE ATLAS, and feed GRCortex AI as compliance evidence for the EU AI Act, NIS2, ISO/IEC 42001 and NIST AI RMF, so results hold up in front of a regulator or a board.
Continuous AI Red Teaming vs Point-in-Time Testing
| Capability | Hexashield AI | Point-in-Time Testing |
|---|---|---|
| Testing cadence | Continuous, scheduled runs | Once, before launch |
| Attack coverage | Prompt injection, jailbreaks, data exposure, model abuse | Limited to what a manual reviewer thought to try |
| Runtime protection | Guardrails enforced inline, live | None once the report ships |
| Evidence | Generated automatically, always current | Assembled by hand, ages quickly |
| Framework mapping | OWASP LLM Top 10, OWASP Agentic, MITRE ATLAS | Ad hoc |
Results from Active AI Security Deployments
A healthcare provider running Hexashield AI found and closed more than 80 high- and medium-severity AI risks, with a retest error rate under 3%.
Cygeniq's Closed-loop platform was placed among the top two at one of the top global banks "Protect the Firm" Global Innovation Forum. Cygeniq was named a "Top 10 Enterprise AI Innovation Company" by Plug and Play (Seattle, August 2025) and is backed by NVIDIA Inception, AWS Startups and Microsoft for Startups.
80+ high- and medium-severity AI risks closedat one healthcare provider, retest error rate under 3%Frequently Asked Questions
What is AI red teaming?
AI red teaming is the practice of testing an LLM, a RAG pipeline or an AI agent with adversarial prompts and attack scenarios to find unsafe or manipulated behavior before an attacker does. Because models change as they are updated or connected to new data, effective AI red teaming must run continuously, not just once before launch.
How do you continuously red team LLMs and AI agents?
Continuous red teaming runs scheduled adversarial tests using a library of attack scenarios covering prompt injection, jailbreaks, data exposure and model abuse. Each run scores current exposure, flags anything a recent model or prompt change introduced, and feeds the result into a risk dashboard so a security team can track exposure over time instead of relying on a single snapshot.
How do runtime guardrails stop prompt injection?
Runtime guardrails check every prompt before it reaches a model and every response before it reaches a user, at the point the system is actually running. They can block or flag known injection patterns and policy violations directly, so protection does not depend only on how the model itself was trained.
How is Hexashield AI different from a standalone guardrail or LLM firewall?
A guardrail tool checks prompts and output at runtime but does not tell you what AI you have, whether it was tested, how exposed it is or how to prove it. Hexashield AI adds discovery and the AI Inventory, continuous red teaming, drift monitoring and a live risk score. Its findings flow into GRCortex AI as compliance evidence and into CyberTix AI as detection context.
What is LLM red teaming?
LLM red teaming applies adversarial prompts and attack scenarios to a large language model to test for prompt injection, jailbreaks, data exposure, unsafe output and other model abuse. In Hexashield AI, this testing runs continuously rather than as a single pre-launch pass.
What is AI runtime monitoring?
AI runtime monitoring watches models, RAG pipelines and agents after deployment. Hexashield AI scores prompts, outputs and agent actions as they happen, monitors vulnerabilities and model drift, and keeps testing active while the AI system is running.
How does Hexashield AI support AI BOM and shadow AI detection?
Hexashield AI discovers and inventories models, agents, copilots and RAG systems across IT and OT, including systems that were not registered. This creates an AI Inventory or AI BOM that can be connected to risk scoring, testing and governance.
See Where Your AI Systems Are Exposed Before Someone Else Finds Out
Book a walkthrough of Hexashield AI: live risk scoring, adversarial testing and runtime guardrails, shown against systems like the ones you are already running.
